









BlogB2B Marketing Attribution
MMM vs MTA: Which One a Lead Gen Team Actually Needs
Marketing mix modeling and multi-touch attribution answer different questions from different data. This guide compares them side by side, covers Robyn and Meridian, shows why a typical lead gen budget struggles to feed an MMM, and where incrementality tests calibrate both.

Contents
Summarise this article with AI
Opens the page with a ready prompt in:


Nothing is sent until you pick a service.
Ask a measurement vendor whether you need marketing mix modeling or multi-touch attribution and the answer usually matches what the vendor sells. The honest answer is less convenient: they are two different instruments, they answer two different questions, and each one needs a kind of data the other does not.
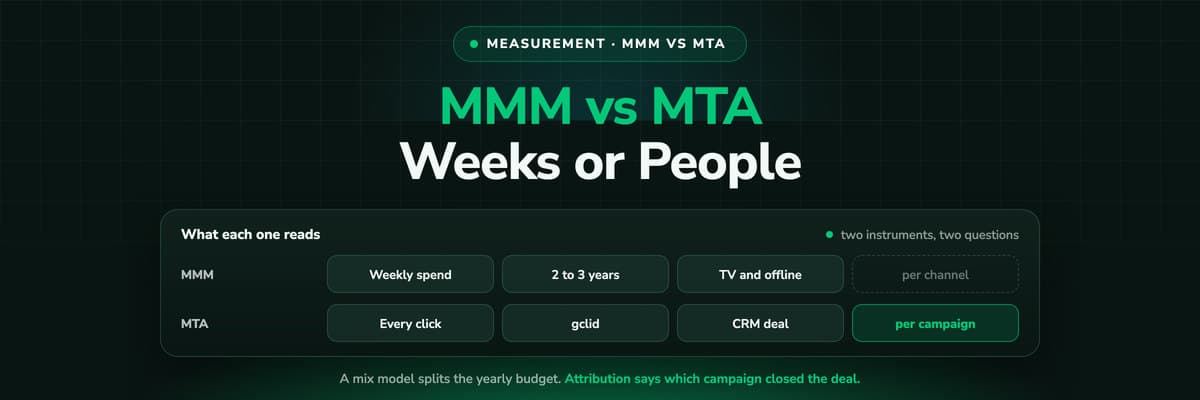
Multi-touch attribution (MTA) follows people. It records the clicks that brought each lead and credits them with the deal that lead became. Marketing mix modeling (MMM) follows weeks. It sets total spend per channel against a total outcome over two or three years and estimates how much of the outcome each channel explains.
This guide is written for lead generation and B2B teams, where the outcome is a qualified lead or a won deal in the CRM, not a checkout. It compares the two side by side, covers the open source models from Meta and Google, shows why a typical lead gen budget struggles to feed an MMM, and places incrementality tests where they belong: as the calibration for both.
Quick Summary: MMM vs MTA in One Paragraph
In short
Multi-touch attribution credits the touchpoints in each person's journey with the conversion or deal that person produced, using user-level click data, so it is fast, granular down to the campaign and keyword, and blind to anything that leaves no click. Marketing mix modeling regresses weekly spend per channel against a weekly outcome over two years or more, so it covers TV, radio, print and impressions that nobody clicked, needs no user-level data, and answers only at channel level, months later. MTA tells you which campaign produced which deal; MMM tells you how much a channel adds in aggregate. Neither proves cause on its own, which is why incrementality tests are used to calibrate both. For most lead generation teams, with a few digital channels and dozens rather than thousands of deals a week, CRM-based attribution plus an occasional holdout test is the right start, and an MMM becomes worth it once offline media, several years of stable weekly data and a budget that varies are all in place.
If your question is the narrower one, whether attribution or a lift test should decide a budget, read incrementality vs attribution. If you want the definitions of lift and iROAS, the glossary entry on incrementality has them.
What MMM and MTA Are
Both try to say how much of your result each channel deserves. They disagree about the unit of evidence: one looks at people, the other at periods.
Multi-touch attribution (MTA)
Records the touchpoints of each person who converts (ad clicks, organic visits, referrals) and splits the credit for their conversion across them by a model: first click, last click, linear, time decay, position based or data-driven.
Marketing mix modeling (MMM)
A statistical model fitted to aggregated time series: spend or exposure per channel per week, plus trend, seasonality, price and other controls, against a weekly outcome. It estimates each channel's contribution and its diminishing returns.
Incrementality testing
An experiment, not a model: one group or region sees the ads, a comparable one does not, and the difference is the effect. Used to check and calibrate both of the above.
The names cause some of the confusion. "Attribution" in MMM vendor copy often means MTA specifically, while the word itself covers any method of assigning credit, including the platforms' own reporting. In this guide MTA means multi-touch attribution on your own first-party click data joined to the CRM, which is a different thing from the totals in Ads Manager. The glossary entry on attribution models covers the rules for splitting credit.
MMM vs MTA Side by Side
The differences follow from the unit of evidence. Once you know a method looks at weeks rather than people, most of the rows below write themselves.
Marketing mix modeling vs multi-touch attribution
| Multi-touch attribution | Marketing mix modeling | |
|---|---|---|
| Data | User-level: clicks, visits, click IDs, joined to leads and deals | Aggregated: weekly spend or exposure per channel, weekly outcome, controls |
| Granularity | Channel, campaign, ad set, ad, keyword, landing page | Channel, sometimes a split within a large channel |
| Speed | Daily, as deals close | A model refit per quarter or half year |
| History needed | Starts the day tracking runs | Two to three years of weekly data, per Robyn and Meridian's own guides |
| Channels covered | Anything that produces a visit: paid, organic, email, referral | Anything with a weekly spend or exposure: also TV, radio, print, out of home |
| Blind to | Impressions nobody clicked, offline media, people who decline consent | Anything below channel level, and anything whose spend never varies |
| Privacy | Needs consent and first-party data per person | Aggregated figures only, no personal data |
| Causal? | No: it records who was there, not who made the difference | Partly: a regression estimate, only as good as its variation and assumptions |
| Decisions it drives | Which campaign, keyword or creative to scale or cut, lead quality per source, what to send back to bidding | How to split the annual budget across channels, where returns flatten, whether offline media pays |
Read the last row twice. The two methods are not rivals for the same decision. A team that asks MMM which ad set to pause and MTA whether television works will be disappointed by both.
Marketing Mix Modeling Explained in Plain Words
An MMM is a regression with two adjustments that make it fit how advertising behaves. The detail varies by model, but the shape is common to all of them.
- A baselineWhat the business would sell or book with no marketing at all: trend, seasonality, holidays, price changes, a competitor's launch. Everything not explained by the baseline is left for the channels.
- Adstock, or carry-overAn ad seen this week still has some effect next week. The model spreads each week's spend forward with a decay, so a burst of TV in March is allowed to keep working in April.
- Saturation, or diminishing returnsDoubling a channel's spend does not double its result. A response curve flattens as spend rises, which is what lets an MMM say where the next euro is worth least.
- Budget allocationWith a curve per channel, the model can propose a split of a fixed budget that it expects to return more. The proposal is only as good as the curves, and the curves only as good as the data.
The weakness sits in the middle of the method. A regression can only learn from what moved. Meta's Robyn guide gives the example directly: if sales vary week to week but TV spend stayed constant, the model has difficulty determining how TV affected sales. Channels that are always on, at a budget that only ever grows, are the hardest for an MMM to read.
Multi-Touch Attribution and Its Limits
MTA is the opposite trade. It gives you detail and speed, and it gives up anything that does not leave a click behind.
Done properly for lead generation, MTA records every visit with its UTM parameters and click IDs at the moment of the click, joins the anonymous visitor to a person when they fill in a form, call or book, and follows that person's record through the CRM stages to the closed deal. You can then ask which campaigns produced deals rather than form fills, what each keyword's leads were worth, and how the answer changes between a first click and a last click model. None of that is possible with weekly totals.
- It cannot see what was not clicked. A YouTube ad, a podcast read or a billboard that sent someone to search your brand shows up as brand search. MMM can credit it; MTA cannot. The click-through vs view-through guide covers why platform view-throughs do not fill the gap.
- It does not measure cause. A retargeting ad clicked by somebody who was already about to book gets credit for a deal it did not make. MTA tells you who was present at a conversion, not who changed it.
- It loses people who decline consent. A visitor who declines is not measured, and that share differs by country and audience.
- Platform MTA is not your MTA. Each ad platform's own attribution counts only its own touchpoints and claims every conversion it touched, so four dashboards sum to more than the CRM.
The Open Source MMMs: Robyn and Meridian
Two of the largest ad platforms publish free MMM code, which has made in-house modeling realistic for teams with an analyst. Both were read on their own pages on 7 October 2026.
The two open source marketing mix models, and Meta's geo experiment package
| Robyn | Meridian | GeoLift | |
|---|---|---|---|
| From | Meta Marketing Science | Meta (facebookincubator) | |
| What it is | MMM package | MMM framework | Geo experiment package, not an MMM |
| Released | November 2021; Python beta announced December 2024 | Open to everyone 29 January 2025 | Open source on GitHub |
| Language | R on CRAN, Python in beta | Python | R |
| Method | Ridge regression, evolutionary hyperparameter search, decomposition of trend and season | Bayesian causal inference, sampled with NUTS | Synthetic control on matched markets |
| Calibration | Recommends calibrating with experiments | Takes experiments and other priors | Produces the experiment results |
| Licence | MIT | Apache 2.0 | MIT |
Robyn describes itself as especially suitable for digital and direct response advertisers with rich data sources. Meridian encourages geo-level data where it exists but can run on national data, and can use reach and frequency. Google launched a partner programme of over 20 measurement firms alongside the general release, which says something about the effort: free code is not a free model. Somebody still has to collect the data, choose the priors and controls, and defend the output.
Platform code, platform incentives?
A fair question, and the code is open precisely so it can be checked. The model is fitted to your data, not the platform's, and the result depends on what you feed it. Treat a platform-built MMM like any other: calibrate it with your own experiments.
What an MMM Needs, and Why Lead Gen Struggles to Feed One
Both open source projects publish their own data guidance, and it is the most useful thing to read before buying any MMM. The numbers are stricter than most vendor pitches suggest.
- History. Robyn's analyst guide says an MMM needs a minimum of two years of weekly data, and four to five years if the data is monthly. Meridian's guide goes further for a national model: two years of weekly data, 104 points, gives four data points per parameter, which it calls too low to estimate reliably, and it prefers three years.
- Rows per variable. Robyn recommends about ten observations per independent variable. Every channel, control and seasonal term is a variable.
- Variation. Spend has to move, independently per channel, or the model cannot tell the channels apart.
- Geography helps. Meridian multiplies the data points by modeling regions, which is why it encourages geo-level data where it exists.
Now take an ordinary lead gen account. Five paid channels, two years of weekly data, plus trend, season and two controls such as a price change and the sales team's headcount: nine variables against 104 weeks, or 11.6 rows each. That passes Robyn's rule of thumb, barely, and fails Meridian's preference for a national model. Add a sixth channel or a third control and the margin is gone.
The outcome is the bigger problem. An e-commerce brand fits its model to thousands of orders a week. A lead gen business that cares about revenue fits it to won deals, and 18 won deals a week is a healthy B2B pipeline. If deals arrive more or less independently, chance alone moves a week of 18 by about four either way (the square root of 18 is 4.24), so a normal week runs from about 14 to 22 with nothing changed. A LinkedIn budget at 10% of a €40,000 month, about €920 a week, has to show its effect inside that noise.
- The sales cycle outlasts the adstockA deal that closes 90 days after the first click puts the effect of this week's spend three months downstream. Modeling on qualified leads is faster but measures a step that is not revenue.
- Always-on budgets do not varyMany lead gen accounts run every channel all year at a slowly rising budget. That is good management and bad data for a regression.
- Sales capacity is a hidden variableBooked calls depend on how many reps were free to take them. If headcount changed, it belongs in the model as a control, or the model will credit marketing with a hiring decision.
MMM vs Incrementality: Where Tests Sit
Incrementality is not a third rival. It is a measurement of one thing at one time, and both MMM and MTA get better when they are checked against it.
An incrementality test, a holdout or a geo experiment, answers one question with real causal evidence: would these conversions have happened without this channel, over these weeks, at this spend? It answers nothing else. It does not split a budget across eight channels or say which keyword works. MMM and MTA do those jobs, and both are estimates. The tests are what keep the estimates honest.
Three methods, three questions
| Method | Question it answers | How often |
|---|---|---|
| MTA | Which campaigns, ads and keywords produced which leads and deals? | Every day |
| MMM | How much does each channel add across the year, and where do returns flatten? | Every quarter or half year |
| Incrementality test | Did this channel cause these results, or would they have happened anyway? | A few times a year, per channel in question |
Robyn's own guide strongly recommends calibrating an MMM with experimental results it calls the ground truth, and running incrementality studies on a regular basis. Meridian takes experiment results as priors. Both projects treat an MMM without tests as a model you have no way of checking, and the same is true of MTA.
How a Lift Test Calibrates MTA and MMM
Calibration means using the test's answer to correct the model's. The arithmetic for MTA is simple enough to do on a napkin.
Last quarter MTA credited retargeting with 30 deals; a geo holdout found 12 incremental. Ratio 0.4. This quarter MTA credits 35, so read it as about 14.
The ratio is specific to one channel, one period and one setup. Retargeting and brand search usually come out well below 1, because they reach people who were already on their way; a prospecting channel can come out near or above it, because it starts journeys that MTA credits elsewhere. Retest when the budget, the audience or the creative changes a lot.
For an MMM the test result goes in as a prior or a constraint: the model is told that this channel's effect over those weeks was about this much, and fits everything else around it. Both open source projects document how. For running the test itself on CRM deals, incrementality testing for lead gen walks through a geo holdout step by step, and the incrementality calculator does the lift arithmetic.
Which One You Need: A Decision Guide
The budget bands below are our rule of thumb, not a published threshold. What matters more than spend is the shape of the account: how many channels, whether any are offline, and how many outcomes a week the model would have to learn from.
MMM, MTA and tests by account shape
| Account | Start with | Add later |
|---|---|---|
| Lead gen or B2B, 2 to 4 digital channels, tens of deals a month | MTA on first-party clicks joined to CRM deals | A holdout on retargeting or brand search before raising either |
| Lead gen or B2B, 5 or more channels, a growing budget, offline events or sponsorships | MTA for daily decisions | Geo tests on the two largest channels; an MMM once two to three years of weekly data exist |
| E-commerce or app, thousands of orders a week, mostly digital | MTA plus platform lift tests | An MMM, which the data can now feed |
| Any business with TV, radio, print or out of home as a real share of spend | An MMM for the budget split | MTA for the digital channels underneath it, and tests to calibrate both |
| Agency running many small client accounts | MTA per client workspace | Tests per client where a channel is in question; an MMM rarely fits one client's data |
Verdict
If you cannot yet say which campaign produced last month's deals, an MMM will not tell you. Get the CRM attribution right first, test the channels you doubt, and model the mix when the data is there to feed it.
Triangulation and Unified Marketing Measurement
"Unified marketing measurement" is the name vendors give to running all three methods and reconciling them. The idea is right; the name is often a product.
Triangulation means letting each method do what it is good at and using the others as a check. MTA steers the daily work. The MMM sets the yearly split. Tests settle the arguments where the two disagree, and their results flow back as calibration into both. When MTA says retargeting is your best channel and the MMM says it adds little, that disagreement is not a failure: it is the cue for a holdout.
- One outcome definition for all three. If MTA reads won deals, the MMM qualified leads and the test form fills, nothing reconciles.
- The same channel names. A channel taxonomy agreed once, so that "paid social" means the same spend everywhere.
- A test calendar. Decide which channel gets tested each quarter, so calibration is a habit rather than a reaction.
How LeadJourney Fits
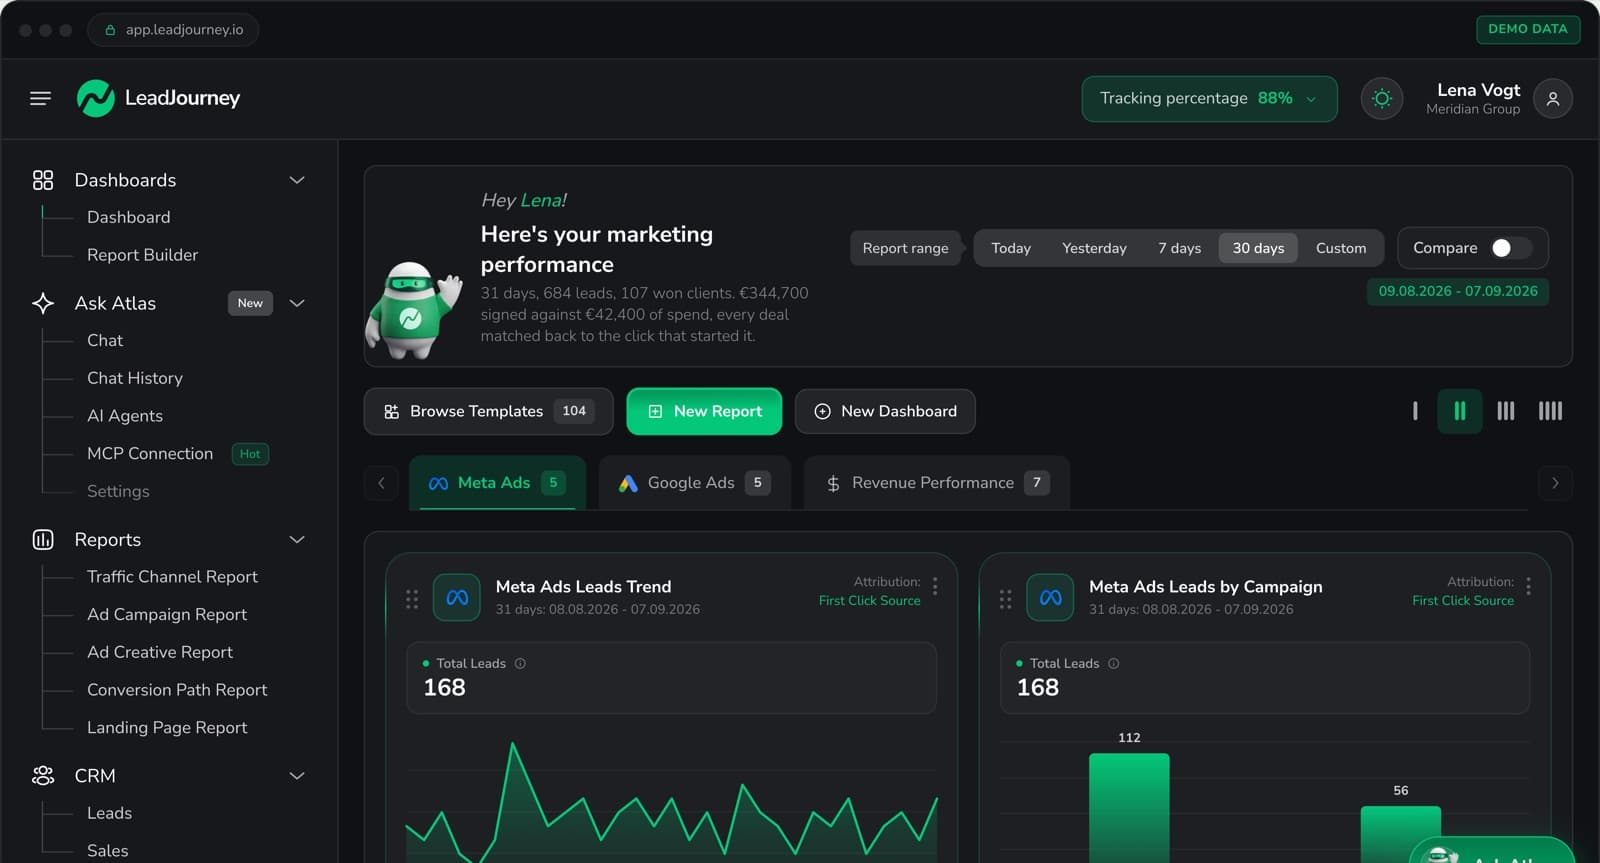
LeadJourney sits on the MTA side of this guide, built for lead generation. One script on the site or in Google Tag Manager records every visit server-side on your own domain, first-party, at 95%+ tracking accuracy, and captures the click IDs (gclid, gbraid, wbraid, fbclid, li_fat_id, msclkid) at the click. The anonymous history is joined to the person at the form, the call or the booking, and native CRM integrations (HubSpot, Salesforce, Pipedrive, Zoho and more) write the source, campaign and journey onto the record and read the stage changes and won deals back. Spend from the ad platforms is joined to leads, deals and revenue per channel, campaign and ad, with first click, last click, linear, time decay and position based switchable on the same events. Setup takes about 21 minutes.
What it does not do, plainly: LeadJourney does not build marketing mix models, run incrementality tests or geo experiments, or count view-throughs, and a visitor who declines consent is not measured. Where it helps the other two methods is the outcome. A lift test or an MMM fitted to form fills measures the wrong thing for lead gen; won deals per campaign and channel, joined to the CRM, are the outcome both should read. And because won deals go back to Meta (Conversions API), Google Ads (offline conversion import), LinkedIn (Conversions API) and Microsoft Ads with the deal value, a platform's own lift study can be set up on deals rather than leads where the study type accepts offline events: check that on the platform before you start. For a DIY geo test, export deals with their source and the customer's region from the CRM.
Five Mistakes When Choosing Between MMM and MTA
- Buying an MMM to fix broken tracking. If deals in the CRM carry no source, the MMM has a weekly total to model and you still cannot say which campaign worked.
- Reading platform dashboards as MTA. Four platforms each claiming their own conversions is not multi-touch attribution; it is four single-touch reports that overlap.
- Modeling on form fills. A channel that brings cheap leads that never close looks best on leads and worst on revenue. Pick the outcome the business is paid for.
- Trusting either without a test. MTA over-credits channels close to the conversion, and an MMM can attribute a season to a channel that happened to rise with it. Tests are the check on both.
- Expecting one number. The methods answer different questions at different speeds. Agree in advance which one decides which kind of budget move.
Further Reading
The rest of this cluster: incrementality for the definitions, incrementality vs attribution for the argument between the two, incrementality testing for lead gen for running a geo holdout on CRM deals, Meta incremental attribution for Meta's setting, and the incrementality calculator. On attribution: attribution models, multi-touch attribution, B2B marketing attribution, cross-channel attribution and click-through vs view-through conversions. For sending deals back to the platforms: offline conversion tracking. Tools that offer modeling next to attribution are compared in LeadJourney vs Rockerbox and LeadJourney vs Northbeam.
FAQ
Frequently Asked Questions
What teams ask before choosing between a mix model and attribution.
What is the difference between MMM and MTA?
Multi-touch attribution follows people: it records the clicks in each converting person's journey and splits the credit for their conversion or deal across them. Marketing mix modeling follows weeks: it fits a statistical model to weekly spend per channel against a weekly outcome, with trend and seasonality as controls, and estimates each channel's contribution. MTA is fast and granular down to the ad and keyword but sees only what was clicked. MMM covers offline media and needs no personal data but answers only per channel, from two years or more of history.
Is MMM better than multi-touch attribution?
Neither is better in general; they drive different decisions. MMM is better for splitting an annual budget across channels, especially when TV, radio or other offline media are a real share of spend. MTA is better for daily decisions inside the digital channels: which campaign, keyword or creative produced deals, and what to send back to the platforms' bidding. Most mature teams use both and calibrate them with incrementality tests. A lead gen team with a few digital channels usually gets more from getting MTA right on CRM deals first.
What is the difference between MMM and incrementality testing?
An MMM is a model that estimates every channel's contribution at once from historical data. An incrementality test is an experiment that measures one channel's causal effect over a defined period by comparing a group or region that saw the ads with one that did not. The test is more trustworthy for the question it answers and answers nothing else. That is why Meta's Robyn guide recommends calibrating an MMM with experimental results, and why Google's Meridian accepts experiment results as priors.
How much data do you need for marketing mix modeling?
Meta's Robyn guide says a minimum of two years of weekly data, or four to five years if the data is monthly, and about ten observations per independent variable. Google's Meridian guide says two years of weekly data is too little for a reliable national model and prefers three, while geo-level data multiplies the data points. Spend also has to vary, per channel, or the model cannot separate the channels. For lead gen, the outcome is often the limit: a few dozen won deals a week is a noisy series to fit.
Are Robyn and Meridian free?
Yes. Robyn is Meta Marketing Science's open source MMM package, released in November 2021, available in R on CRAN with a Python version in beta, under the MIT licence. Meridian is Google's open source MMM framework in Python, under Apache 2.0, opened to everyone on 29 January 2025. The code is free; the work is not. Someone has to collect and clean two or three years of weekly data, choose controls and priors, validate the model and defend the output, which is why Google launched a partner programme alongside Meridian.
Does LeadJourney do marketing mix modeling?
No. LeadJourney does multi-touch attribution for lead generation: it records every click first-party and server-side, joins the visitor to the lead at the form, call or booking, follows the record through the CRM to the won deal, and offers five attribution models on the same events. It does not build MMMs or run incrementality tests. What it provides for both is the outcome: won deals and revenue per campaign and channel, and won deals sent back to Meta, Google Ads, LinkedIn and Microsoft with their value.
Keep reading
More from the blog
 B2B Marketing Attribution
Incrementality vs Attribution: Which Question Each Answers
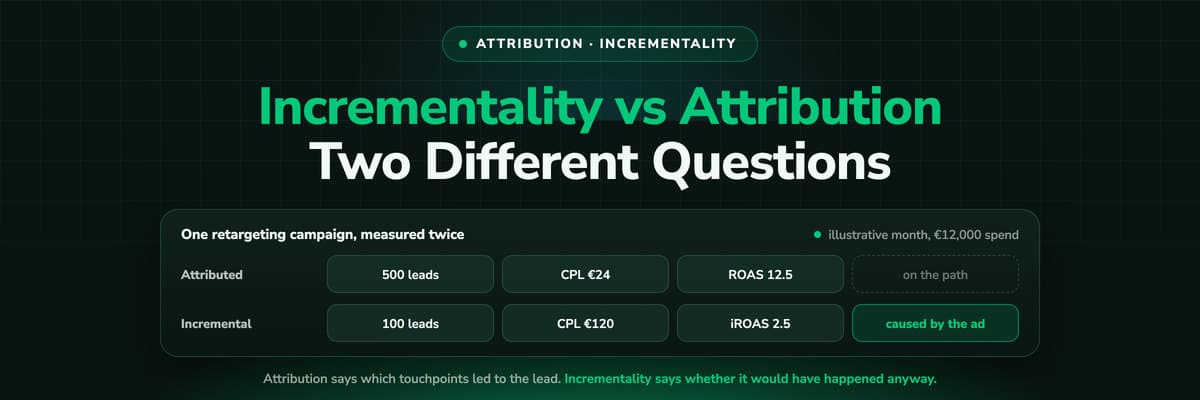
Attribution tells you which touchpoints led to a lead or a deal. Incrementality tells you whether it would have happened anyway. This guide works one retargeting campaign through both, shows where each belongs, and how to combine them when the outcome lives in your CRM.Read the article17 min read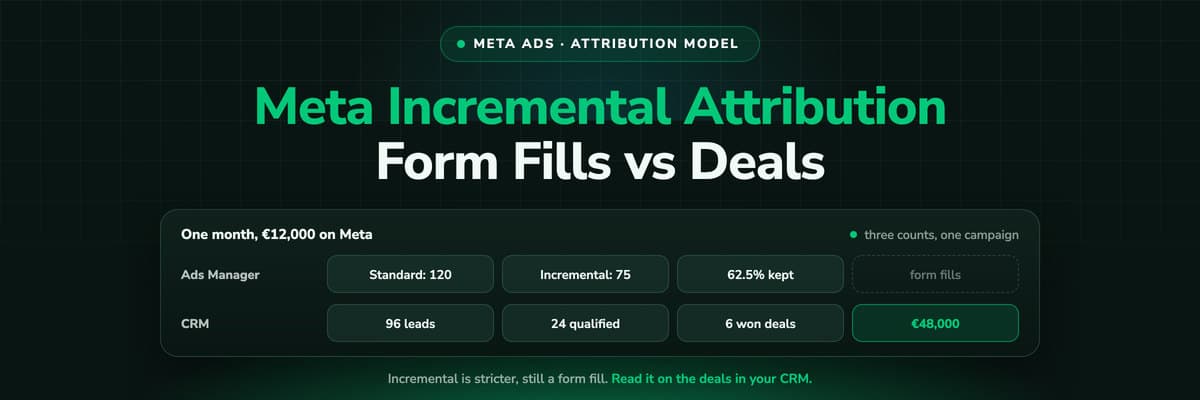 B2B Marketing Attribution
Meta Incremental Attribution: What It Counts for Lead Gen
Meta's incremental attribution model optimises and reports on the conversions its models predict an ad caused, not every conversion inside a window. This guide covers what Meta's own help pages say about it, how it differs from 7-day click 1-day view, why its numbers come out lower, what it cannot see in lead generation, and how to read it next to the deals in your CRM.Read the article17 min read B2B Marketing Attribution
iGaming Attribution: Who Gets Credit for the FTD
The operator's program decides which affiliate gets the player. It does not decide which of your pages, streams or keywords earned the FTD. How the attribution models split one player's FTD, which model fits a CPA, rev share or hybrid deal, and whether to credit the count, the deposit or the NGR the program posts back.Read the article12 min read
Attribution on the deals, not the form fills
Know which campaigns produced your deals before you model the mix
LeadJourney captures every click first-party on your own domain, joins it to the CRM lead and won deal, and sends the revenue back to Meta, Google, LinkedIn and Microsoft. Live in 21 minutes, 14 days free.